
Key takeaways
- In response to a new European Union law, AI platforms are implementing new schemes for watermarking the content they generate.
- ” Anyone who knows the key can determine if it was generated by the platform using it.
- The threat can become greater in the face of an adversarial prompt, in which an attacker attempts to cause a model to carry out a harmful…
What happened
In response to a new European Union law, AI platforms are implementing new schemes for watermarking the content they generate. Anthropic recently disclosed its future Claude models will use SynthID-Text, an approach Google created and released as open source. It uses a secret key that subtly changes the process a model uses for choosing the next word in a sentence.
The one with the higher hidden score wins and advances to the next round. The process continues until a final winning token is determined. More about tournament sampling can be found here and here. Siposova tested the “non-distortionary” configuration of SynthID-Text through Hugging Face’s unmodified SynthIDTextWatermarkLogitsProcessor. She fed harmful prompts into six open-weight models and compared the responses when the watermarking was used and when it wasn’t.
The experiment revealed that the watermarking changed responses to harmful requests, particularly when they were made using prompt-injection techniques. “Watermarking changes refusal behavior on bare harmful requests, but the effect is more pronounced when the same requests are paired with the prompt-injection technique,” Siposova wrote.
” The changes have important safety consequences because they influence not only the LLM responses but also subsequent actions of AI agents relying on the model. “At the model level, this can change safety behavior, including whether the model refuses a harmful request and whether that refusal holds under prompt injection,” the researcher wrote.
“At the agent level, the same sampled tokens can determine which tool is called and what arguments are passed to it. Prompt injection connects these two settings because a weakened refusal becomes more consequential when the model can also act through tools. Such a watermarking procedure can therefore affect both what the model says and what an agent does.
” Also interesting: Model responses behaved differently depending on which secret key was used. There are limitations to the research. It doesn’t test how Claude model responses change under the watermarking. Instead, it tests a half-dozen open-weight models, so the researcher has access to token sampling that could be enabled and disabled during tournament sampling while keeping other settings fixed.
Why it matters
” Anyone who knows the key can determine if it was generated by the platform using it. New research shows that SynthID-Text can change not just word selection but also the tools a model invokes and the chances it will adhere to or disregard safety guardrails it has been trained to follow.
The threat can become greater in the face of an adversarial prompt, in which an attacker attempts to cause a model to carry out a harmful action, such as revealing a password or other sensitive information. Instructions that normally wouldn’t be followed will, in some cases, be performed once the watermarking is deployed.
The finding underscores the need for developers to thoroughly test how their LLMs and agents behave when watermarking is in place. “As compared to the same models without watermarking, it is definitely going to change their behavior, especially when we place it under adversarial conditions, or we make these models call tools when they’re powering an agent,” Andrea Siposova, an AI security researcher at Lasso Security, told Ars.
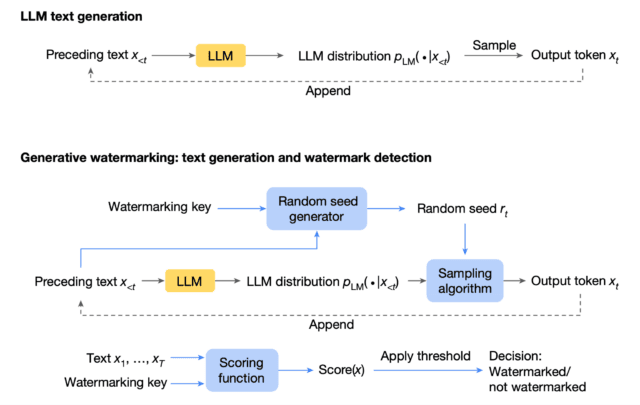
” Watermarking works by embedding a signal that allows output to be identified as AI generated, something known as provenance. SynthID takes the normal sampling process and adds a random seed generator, sampling algorithm, and scoring function to it. Instead of the process using an arbitrary random number generator for next-word selection, the watermarking uses a secret key.
While the word selection is still random, people with knowledge of the key can check the sequence of words to determine the likelihood that the key was used. A key feature of SynthID is something known as tournament sampling. Similar to a sports game, SynthID evaluates large numbers of next-word token candidates. It uses a secret key to assign them probability scores. A pair of tokens competes in a round.
What to watch
The experiments also tested the Hugging Face implementation of SynthID-Text tournament sampling and not the specific implementation Claude models will use. Still, the results show that at least some forms of the watermarking approach may affect model and agent safety. It will be important for red-team hacking exercises to stress-test their platforms to ensure they perform as expected when SynthID is deployed.